Inception AI
Mercury 3
a diffusion language model with a million-token context
Key facts
- 19 Oct 2026
- Released
- 1M tokens
- Context
- $0.10 / $0.35
- Launch input / output
- Hosted API
- Access
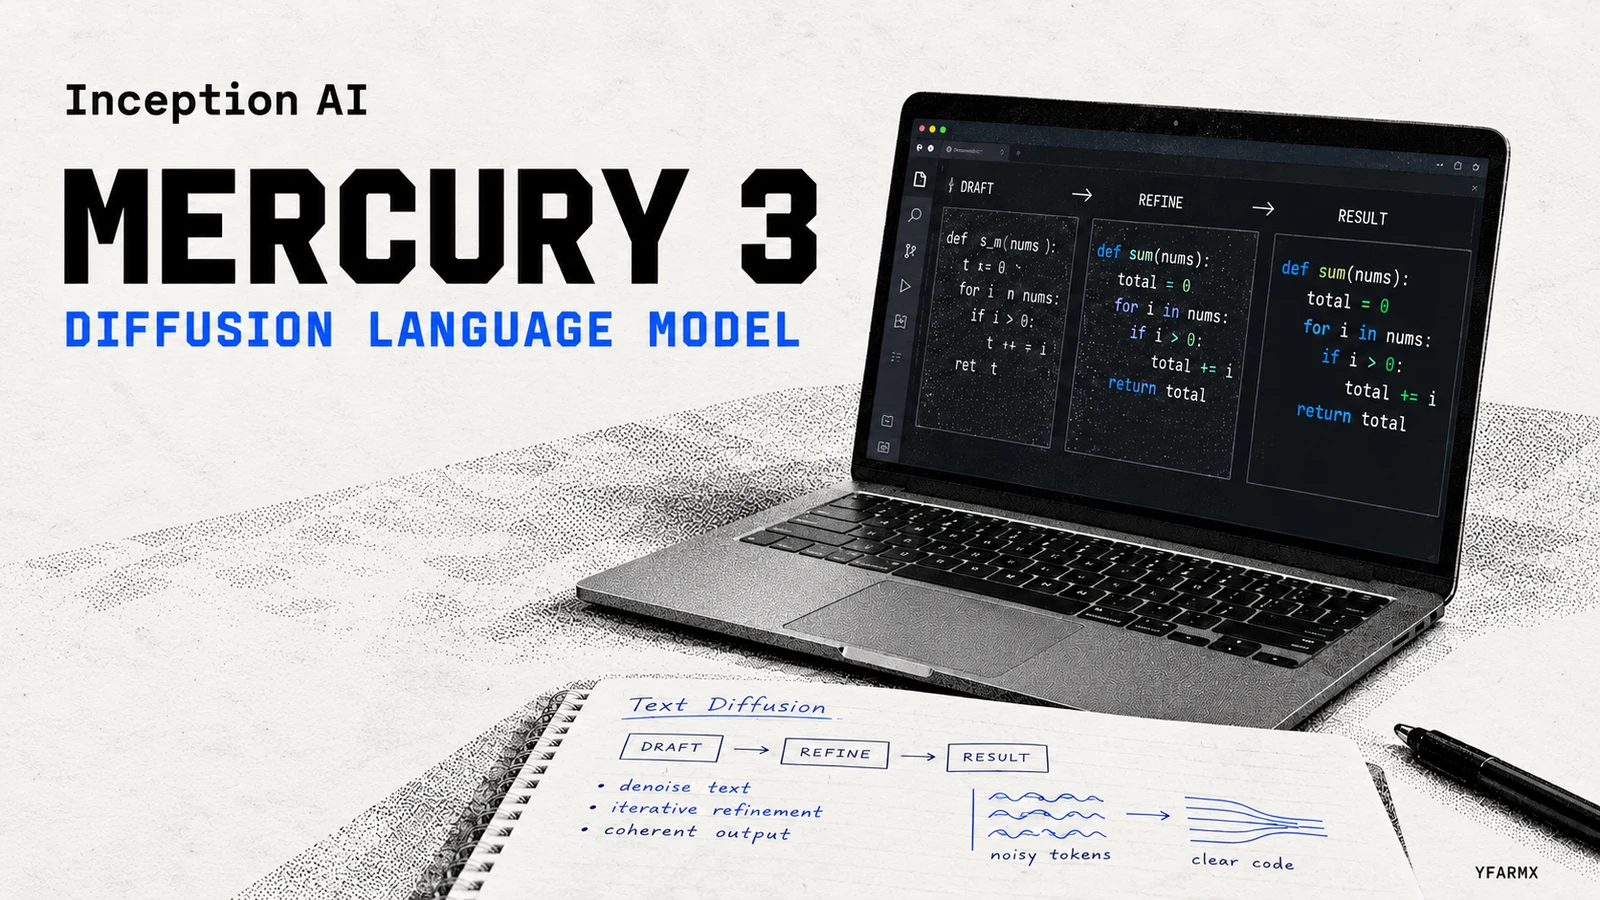
Mercury 3 is a language model that generates and revises text using diffusion. Inception AI launched it on 19 October 2026 for coding, agents and other text tasks.
Mercury 3 is a language model that generates and revises text using diffusion. Inception AI launched it on 19 October 2026 for coding, agents and other text tasks.
Diffusion refines a draft over several steps
A diffusion language model repeatedly improves an initial text representation. This offers a different generation method from a model that writes one token after another. Mercury 3 supports a one-million-token context window, according to Inception’s launch.
The provider reports 1,068 tokens per second in its own NVIDIA GPU test. That is a vendor measurement under its test conditions. A complete application also spends time reading prompts, calling tools and sending data.
Launch discounts halve the standard token prices
Inception lists launch rates of $0.10 per million input tokens and $0.35 per million output tokens, compared with standard rates of $0.20 and $0.70. Cached input receives a 90% discount on the applicable input rate. These prices were checked on 20 October 2026; the launch promotion has its own terms.
Developers use Mercury 3 through hosted services
The launch names Inception’s API, OpenRouter, Baseten and Vercel as access routes. OpenRouter’s model page lists its current hosted offering. Provider support for tools, response formats and caching should be checked for the selected endpoint.
For a coding agent, evaluate whether the model completes the task correctly, how often it needs another attempt, and the cost and time of the complete workflow.
More in Large Language Models
All LLMs →- MiniMaxMiniMax M3.1 Flasha low-cost model for coding agents
- Google DeepMindGemini 4 Argonlonger reasoning, coding and cyber defence
- OpenAIGPT-5.6the flagship from 9 July to 3 September 2026
- OpenAIGPT-6 Astrathe new generation, rolling out from 3 September 2026
- OpenAIGPT-6.1 Solthe upgraded mid-price GPT-6 model, released 29 September 2026
- OpenAIGPT-6 Sol and Lunathe mid-price and budget GPT-6 models, released 22 September 2026