Meituan
LongCat-2.5
open multimodal AI for extended tool tasks
Key facts
- 2 Nov 2026Meituan technical team
- Announced
- 1.6T / ~48Btotal / active, developer figures
- Parameters
- Text + images / textnative visual understanding
- Input / output
- MITpublished weights
- Licence
LongCat-2.5 is Meituan’s model for text, images and extended tasks using software tools. Its published weights use the MIT licence.
LongCat-2.5 is Meituan’s AI model for understanding text and images and carrying out extended tasks with software tools. Meituan’s technical team announced it on 2 November 2026. Its official model repository now publishes weights under the MIT licence.
Visual understanding and tool use share a model
LongCat-2.5 accepts text and images and returns text. Meituan positions it for longer agent tasks, in which a model needs to inspect information, select tools and use their results over several steps. That is different from answering a single isolated question.
Its mixture-of-experts design uses selected portions of the model for each token. Meituan’s technical description gives 1.6 trillion total parameters, with approximately 48 billion activated per token. The hosting platform’s automatic metadata displays a different total. The figures here are explicitly the developer’s architectural description.
Open weights and hosted access are separate choices
The published weights use MIT terms, and the repository links a W4A4 quantised version. A model of this scale still needs substantial deployment resources; an open licence by itself does not make it a small local model. Read the exact checkpoint and serving instructions before sizing hardware.
Meituan also provides chat and API access. The announcement date describes the model launch. The sources checked here do not establish an exact day for the later publication of weights or a current per-token API rate.
Test long tasks from start to finish
Developer benchmarks provide a starting point for comparison. An application-level test should also check whether the model keeps track of earlier instructions, chooses suitable tools and recognises when a tool result is incomplete. Measure completion and errors over the full task, rather than relying only on isolated answers.
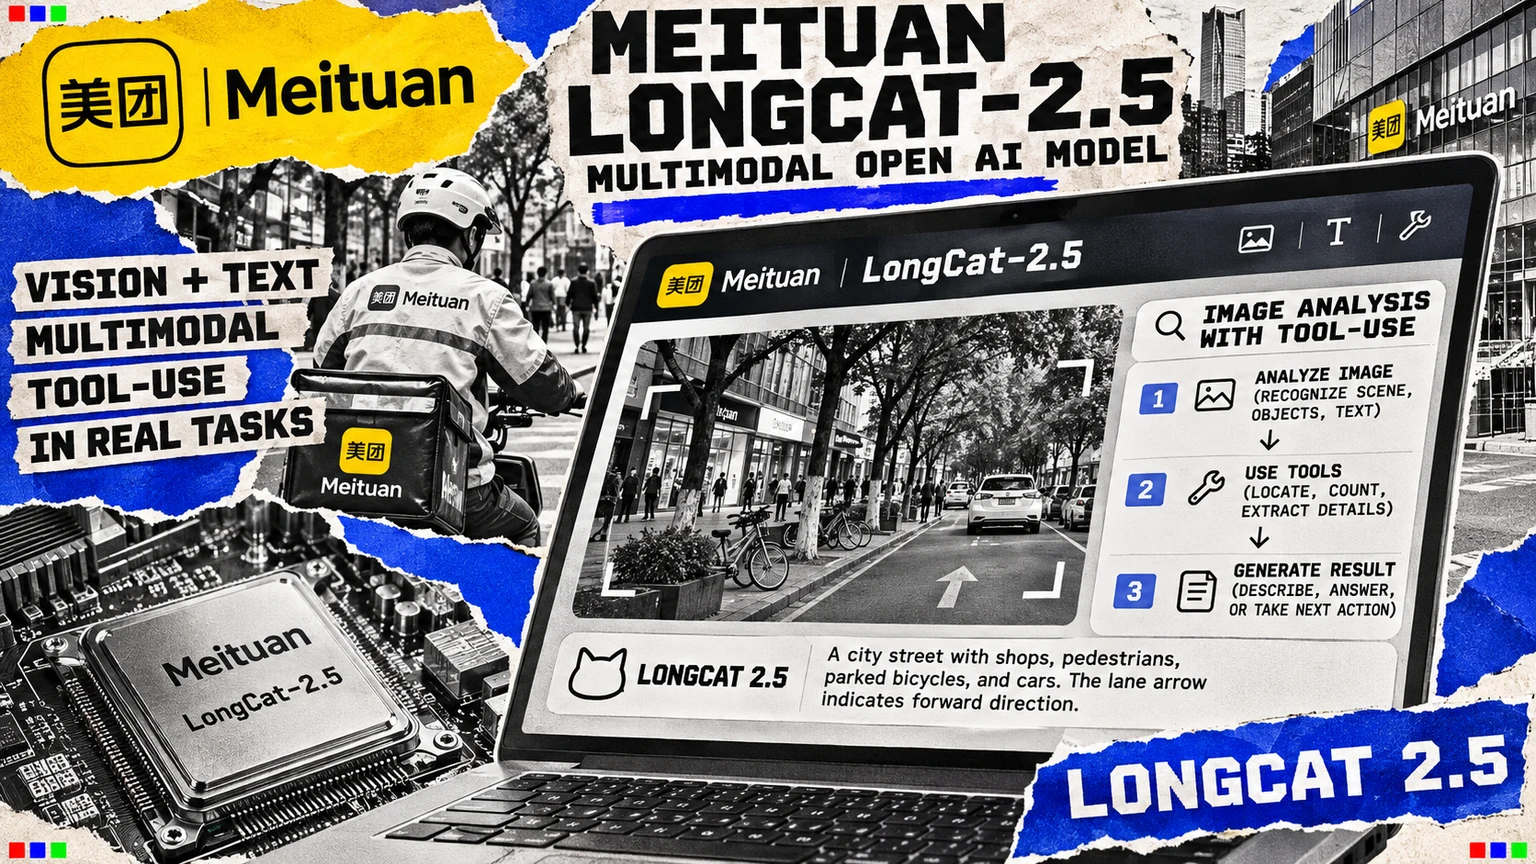
The cover is a conceptual illustration of multimodal model use.
More in Large Language Models
All LLMs →- Google DeepMindGemini 4 Argonlonger reasoning, coding and cyber defence
- OpenAIGPT-5.6the flagship from 9 July to 3 September 2026
- OpenAIGPT-6 Astrathe new generation, rolling out from 3 September 2026
- AnthropicClaude Fable 5.2An AI model for difficult coding, research and long-running tasks
- Google DeepMindGemini 4 CarbonCoding, research and tasks with many steps, now available more widely
- OpenAIGPT-6.1 Solthe upgraded mid-price GPT-6 model, released 29 September 2026